Antiquarian sellers in the UK and Europe reported anonymous bulk orders for obscure titles that investigators say may have been intended for AI training. Court documents reported in the press allege Anthropic's internal 'Project Panama' bought and mechanically opened millions of second‑hand books to scan their pages for model training. The revelations have reignited concerns about copyright, authors' rights, and the rise of low‑cost AI‑generated books, prompting calls for clearer regulation and disclosure.
Anthropic's 'Project Panama' Allegedly Destroyed Millions Of Rare Books To Train AI
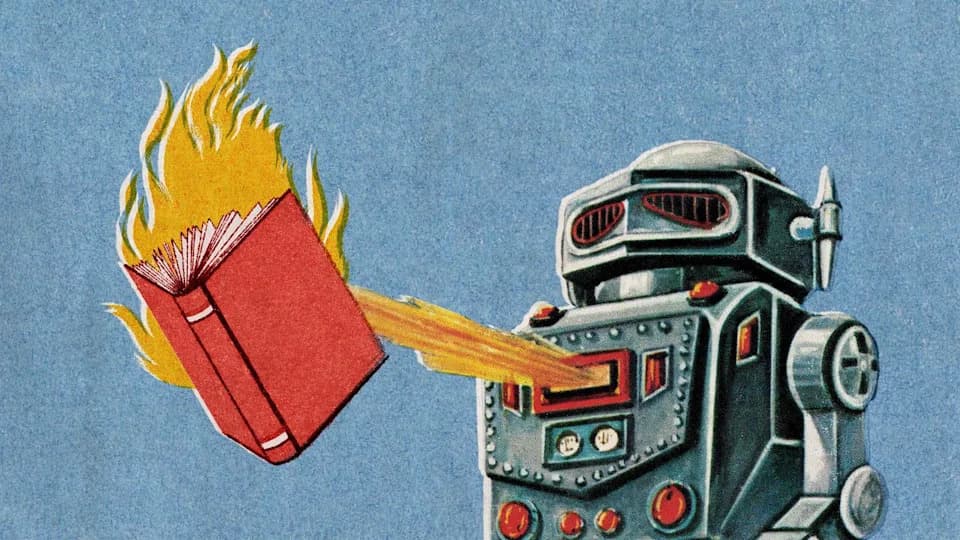
A senior Anthropic executive said that books taught AI systems 'how to write well', as opposed to using 'low-quality internet speak'. | Credit: Illustration by Julia Wytrazek / Getty Images
Antiquarian booksellers across the UK and Europe have reported a wave of suspicious, anonymous purchases of obscure titles that investigators say may be connected to AI training efforts. Court filings and reporting name Anthropic's internal initiative, dubbed Project Panama, as having treated printed books as essential training material for advanced language models.
How The Purchases Worked
Several specialist dealers describe unusually large enquiries from anonymous buyers who requested extra photographs and detailed condition information, then placed bulk orders without identifying themselves or disclosing the books' destination. One London rare‑book seller told reporters that repeated questions about the purchasers' identity went unanswered, raising suspicions that the buyers were sourcing material for a third party.
What Project Panama Allegedly Did
According to recent court documents cited in media reports, Anthropic reportedly purchased millions of second‑hand books, removed their spines with industrial cutting equipment, scanned every page to create training datasets, and recycled the remaining paper. Internal notes allegedly show leaders wanted the work kept confidential; one executive is quoted as saying they did not want it known they were pursuing the project.
"Books teach systems how to write well," one senior Anthropic executive allegedly said, contrasting printed works with what the quote described as "low‑quality internet speak."
Responses, Denials And Legal Questions
Other companies have been named in connection with bulk purchases; for example, Canadian firm Zoom Books has been reported in some accounts but has denied participating in the digitisation and destruction of books for AI training. Observers — including representatives of publishers and booksellers — say these revelations highlight thorny questions about copyright, consent and the preservation of physical culture.
Rights groups and trade bodies note that proving copyright violations can be difficult because national laws differ and legal loopholes remain. Thomas Koch of the German Publishers and Booksellers Association characterized the episode as another example of AI developers using large volumes of copyrighted works without consent or payment, and called for clearer rules and greater transparency.
Broader Industry Concerns
Publishers warn that models trained on copyrighted books can now generate new titles quickly and cheaply, contributing to an influx of low‑cost, AI‑generated books on digital marketplaces. Industry groups are urging national governments and the European Union to update regulation, strengthen disclosure requirements for training datasets, and ensure creators receive fair treatment.
Note: The claims above are drawn from media reporting and court filings cited in contemporary coverage. Some companies named in reporting have denied involvement; legal proceedings and investigations are ongoing.
Help us improve.