Newly unsealed court documents reveal Anthropic bought and physically dismantled millions of books under an internal program called "Project Panama", spending tens of millions to digitize used volumes for training its Claude models. Internal notes reportedly urged secrecy. The disclosures emerged in a copyright lawsuit and have intensified legal scrutiny over how copyrighted works may be used to train AI.
Revealed: Anthropic Bought and 'Destructively Scanned' Millions of Books to Train Claude
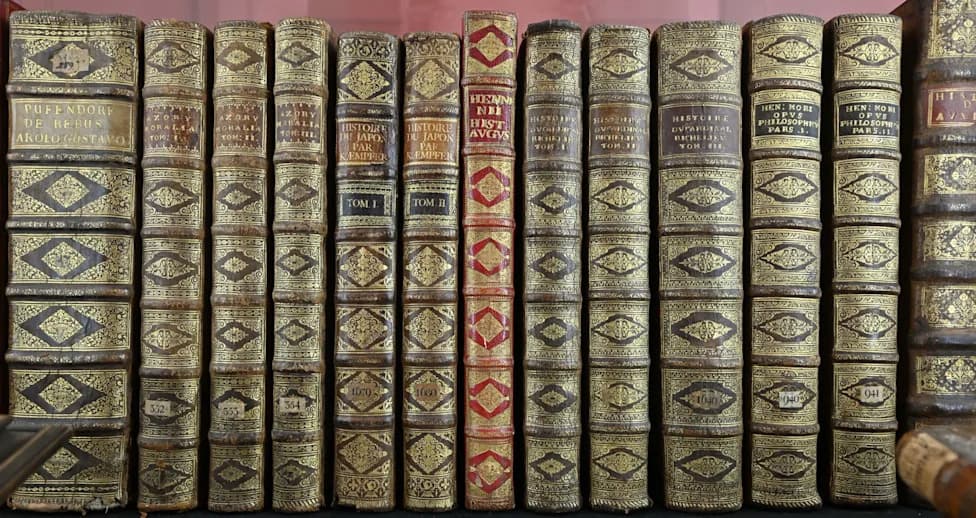
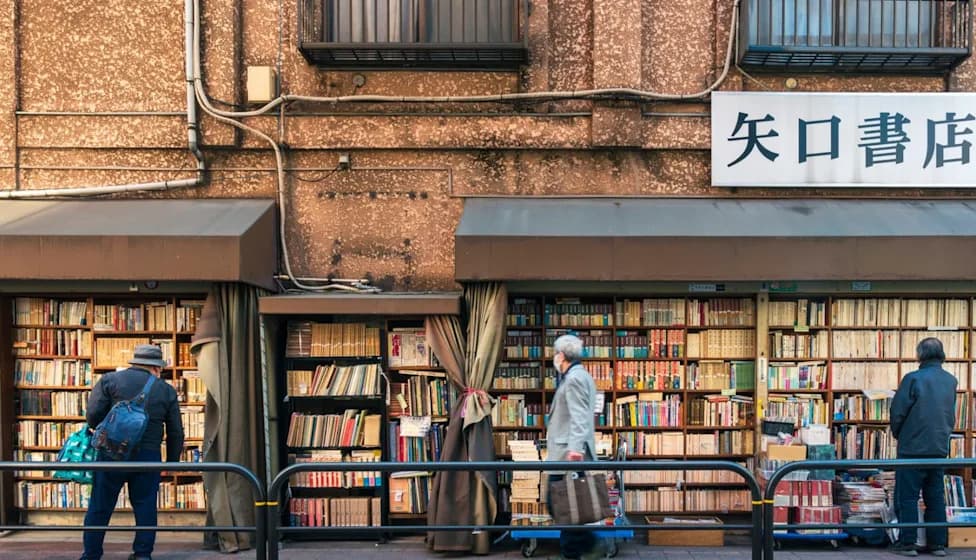
Anthropic spent tens of millions of dollars buying books from used-book sellers before dismantling and digitizing them, according to court filings. Internal planning materials also reportedly noted, "We don't want it to be known that we are working on this." Martin Schutt/dpa
Newly unsealed court filings show that AI startup Anthropic purchased millions of printed books, removed their spines, scanned every page and recycled the remnants as part of an internal effort to produce training data for its Claude models.
The program, internally dubbed "Project Panama", was described in company documents as an attempt to "destructively scan all the books in the world." The filings say Anthropic spent tens of millions of dollars buying used volumes from booksellers before dismantling and digitizing them.
Internal planning notes reportedly included the line:
"We don't want it to be known that we are working on this."
Why Books Were Targeted
The filings indicate Anthropic valued books because professionally edited, long-form texts can teach language models narrative structure, factual consistency and higher-quality writing patterns that are often harder to extract from casual web content.
Legal And Industry Implications
These disclosures surfaced in a copyright lawsuit and raise urgent legal questions about whether and how copyrighted books can be used to train AI systems. U.S. courts are still resolving key issues that could determine rights and responsibilities for authors, publishers and AI developers.
The episode underscores the intense competition among AI companies for high-quality training data and highlights the ethical, legal and reputational risks that can accompany aggressive data-collection strategies.
Help us improve.